Apps built on GMI Cloud
Each demo runs on the same API and compute you build with. Open one, then read the docs.
Community demos
Built by the GMI Cloud community and GMI DevRel. 49 demos, each one a small app that calls GMI inference and returns a result.
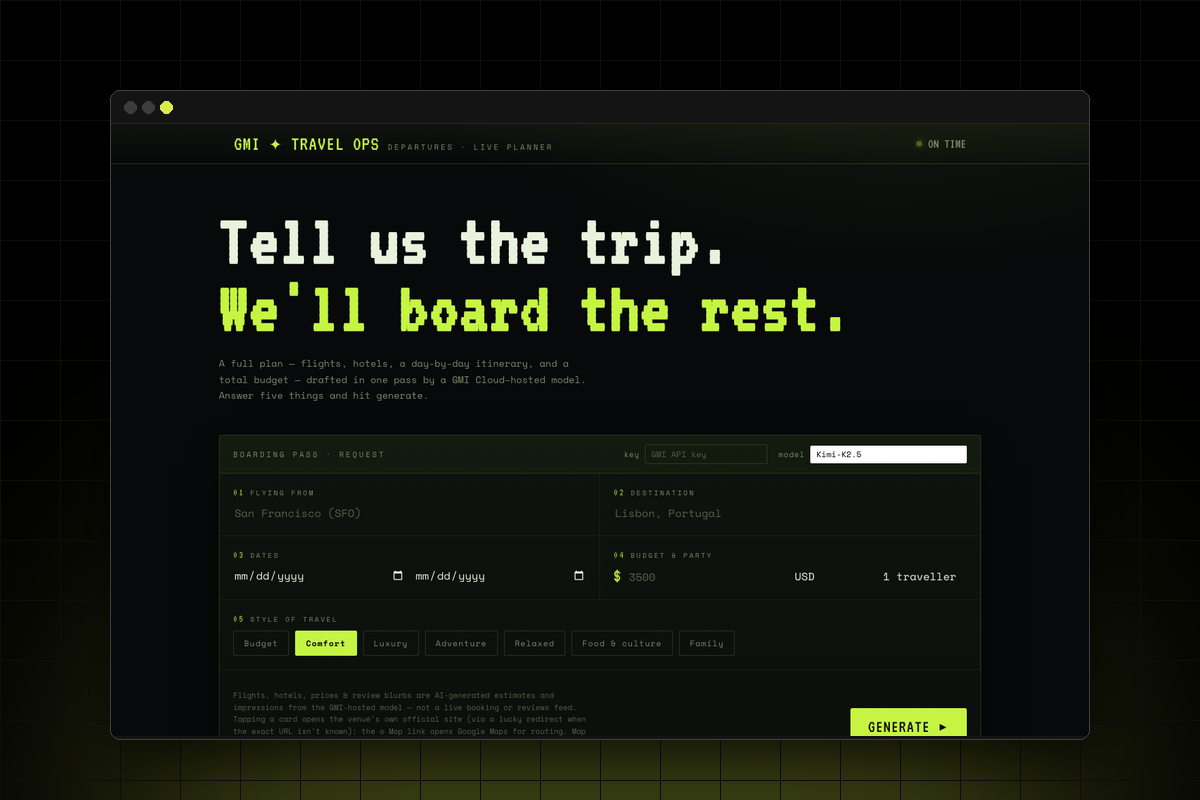
Travel Ops
Answer five questions, pick a model, and a GMI-hosted model drafts flights, hotels, a day-by-day itinerary, food picks, a map and a budget with CC photos.
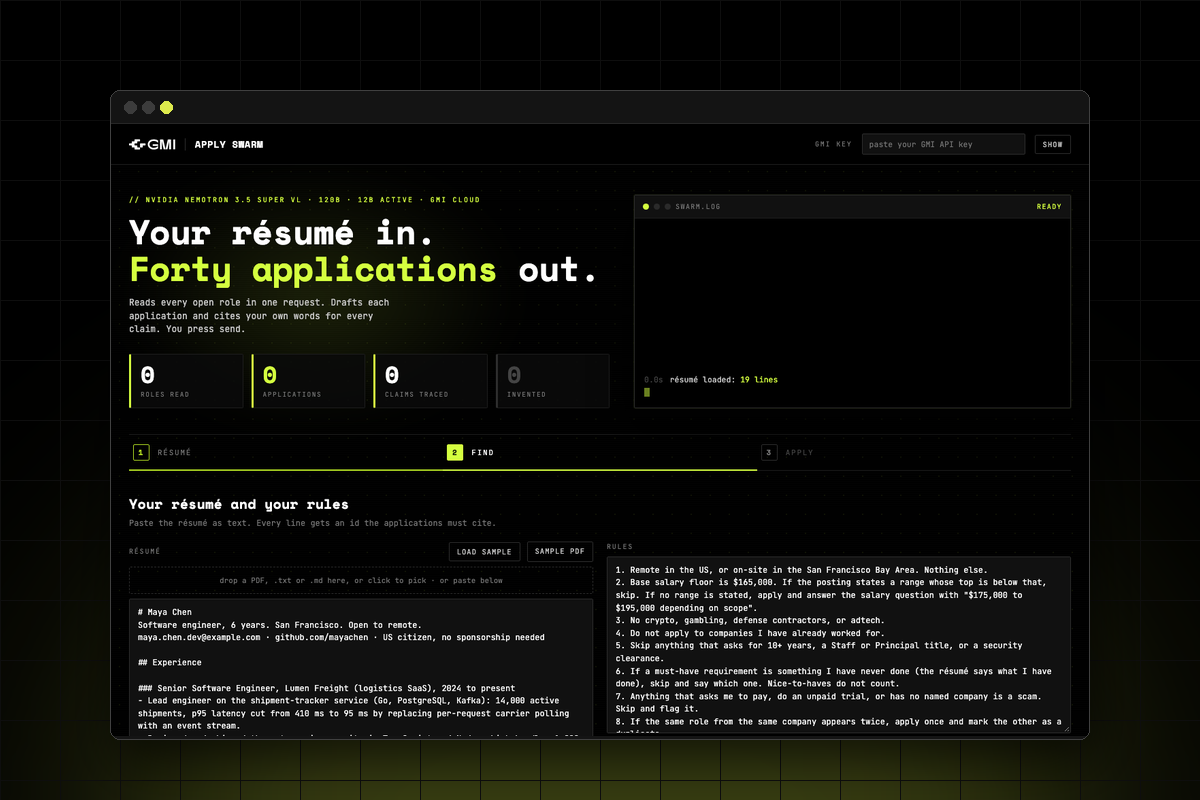
Apply Swarm
Résumé in, live Greenhouse and Lever search, one-call triage, then parallel drafts with per-claim citation checks on Nemotron.
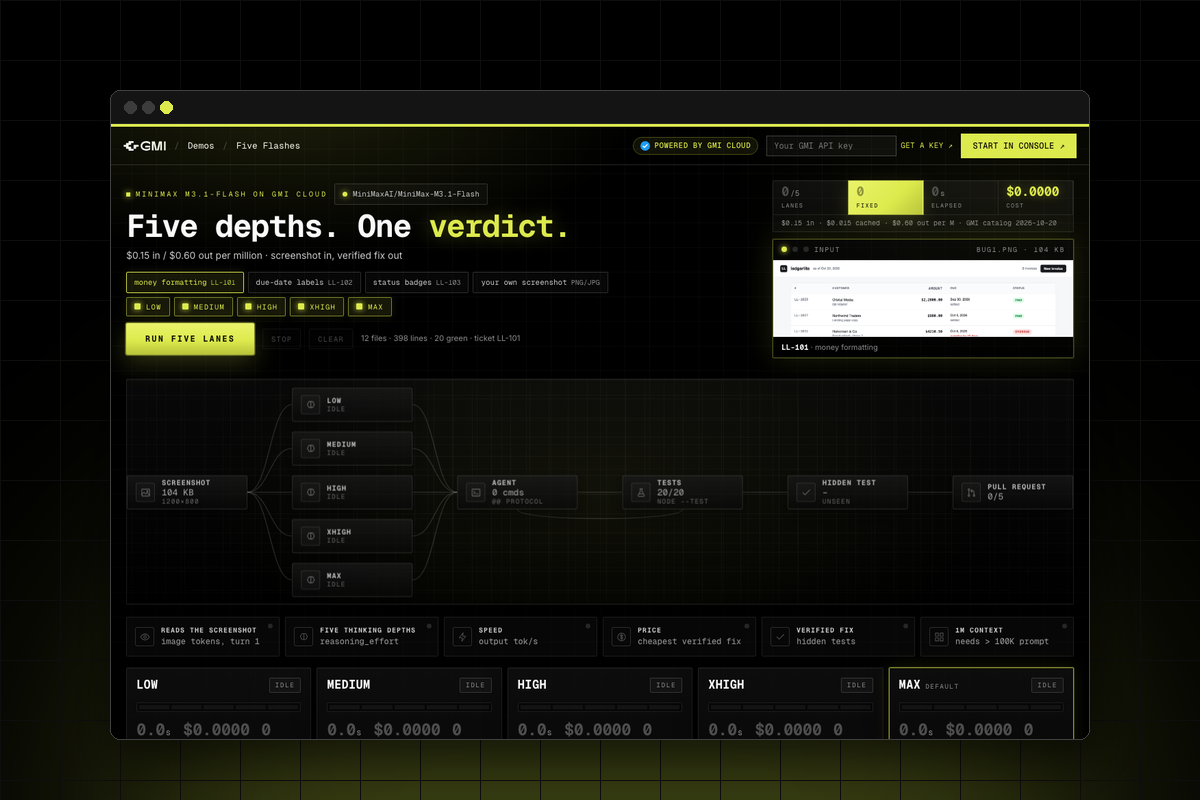
Five Flashes
One bug, five thinking depths: MiniMax M3.1-Flash fixes a dashboard bug from a screenshot in five lanes, one per reasoning_effort, graded by a hidden test.
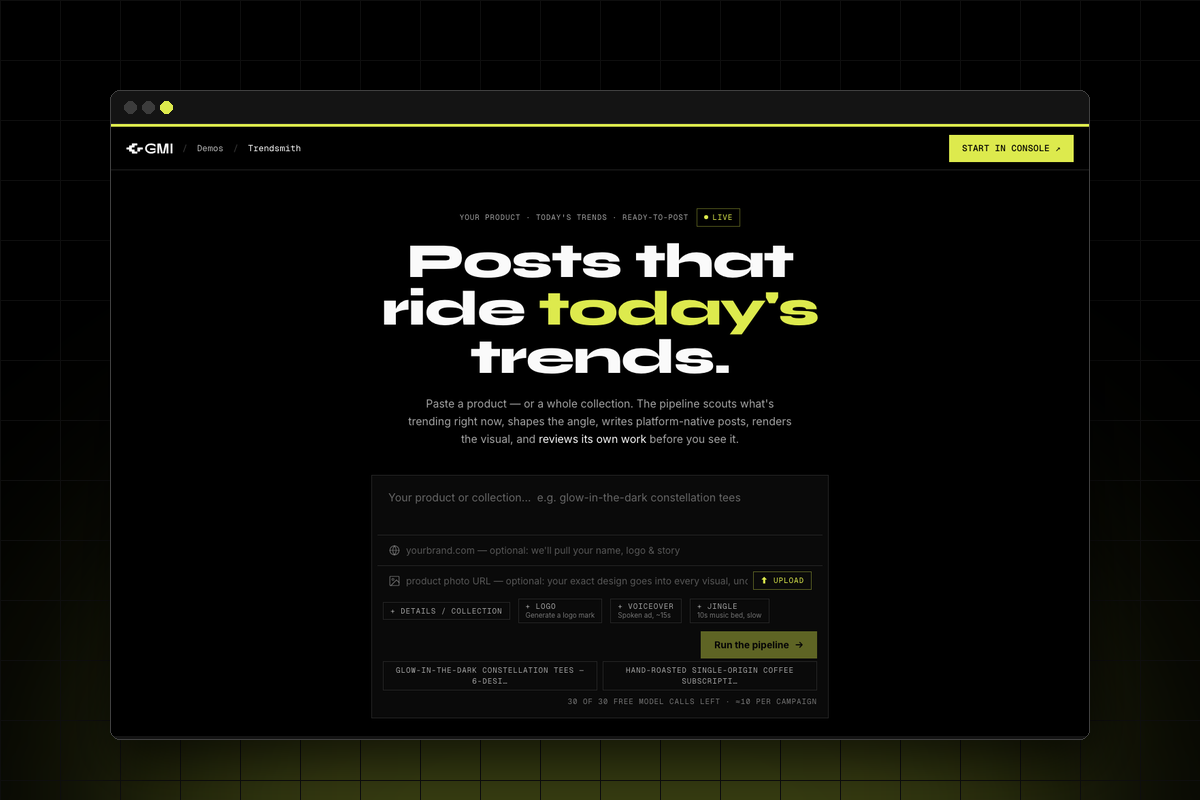
Trendsmith
Paste a product; agents scout today's trends, plan the campaign, write platform-native posts, render the hero visual and review their own work.
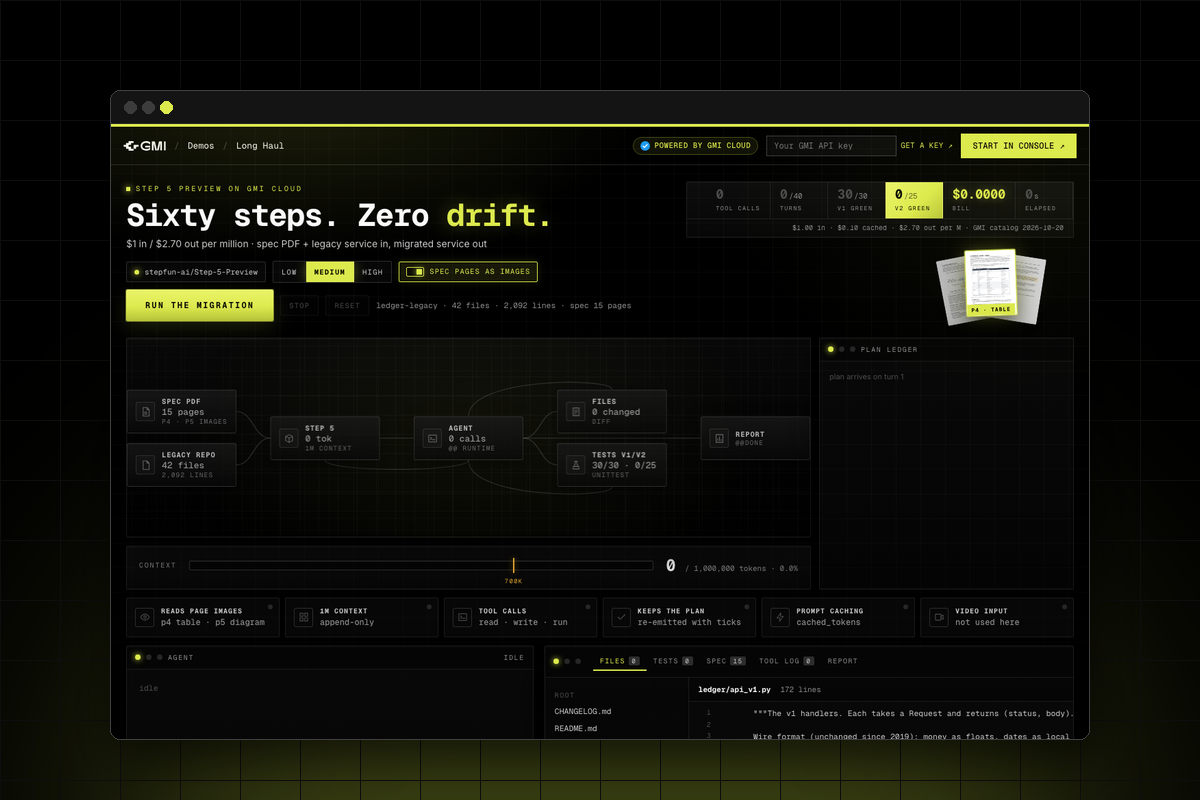
Long Haul
A legacy billing service and a 15-page spec PDF go in; Step 5 Preview plans, reads, writes and runs tests until v2 passes with v1 still green.
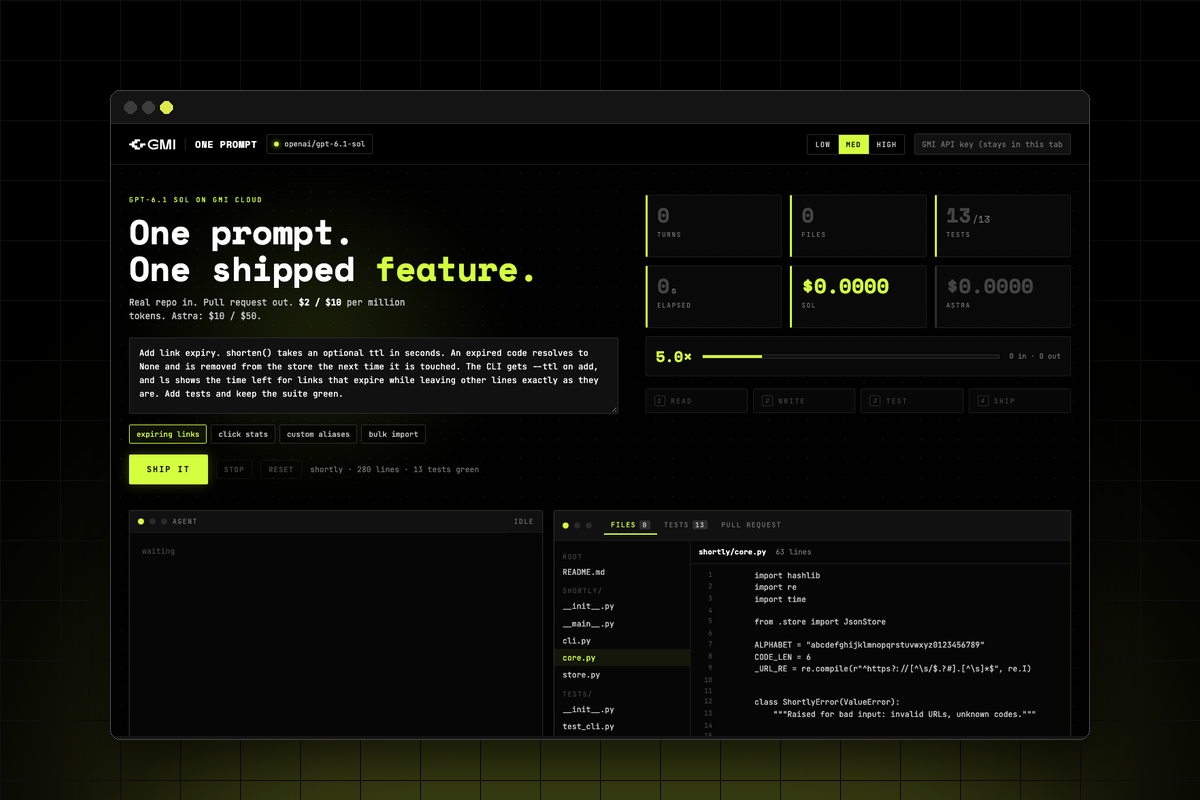
One Prompt
One feature request in, one pull request out: GPT-6.1 Sol reads a small repo, writes code and tests, runs the suite, fixes what breaks, ships a PR.
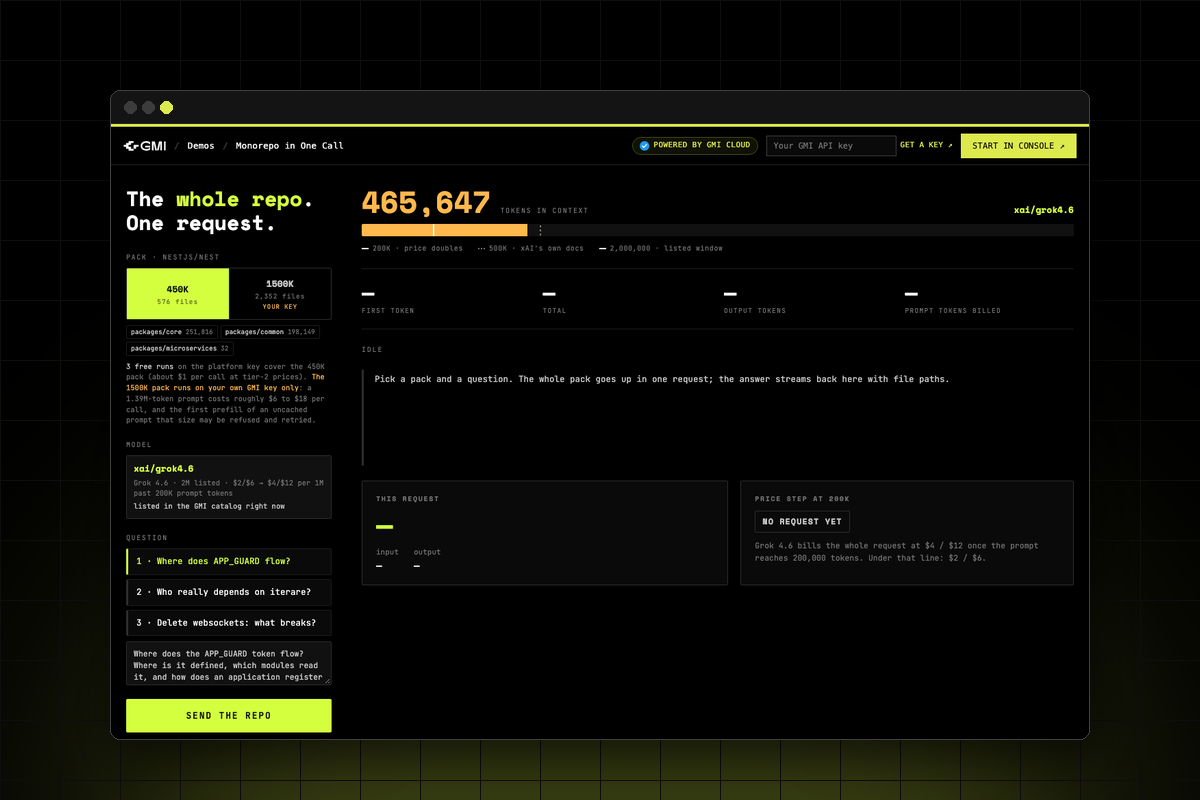
Monorepo in One Call
A whole NestJS monorepo (450K or 1.39M tokens) in one Grok 4.6 request: cross-module answers with file paths, and the bill with its 200K price step.
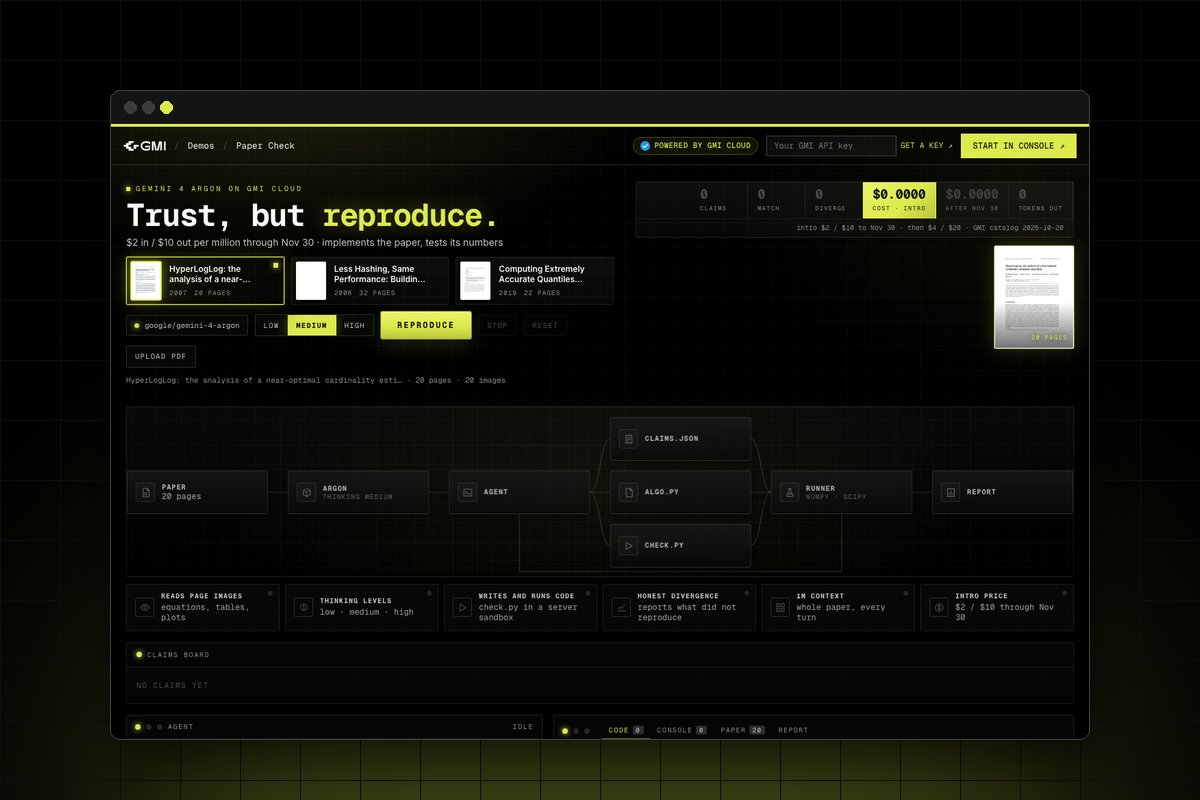
Paper Check
Paper in, reproduction out: Gemini 4 Argon reads a math-heavy PDF, picks its numbers, implements the algorithm, runs a check and reports what reproduced.
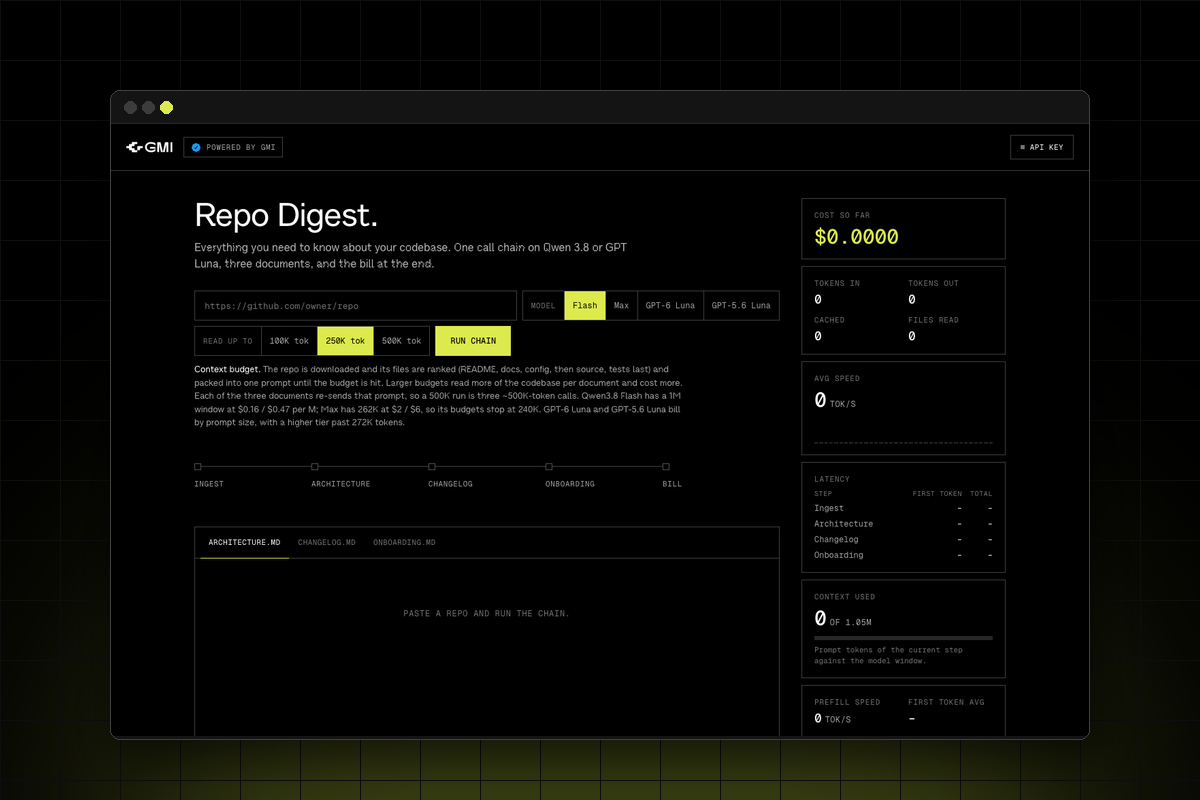
Repo Digest
Paste a GitHub repo: up to 500K tokens of it go through one call chain (architecture, changelog, onboarding) with price, latency and speed tracked live.