developer tools
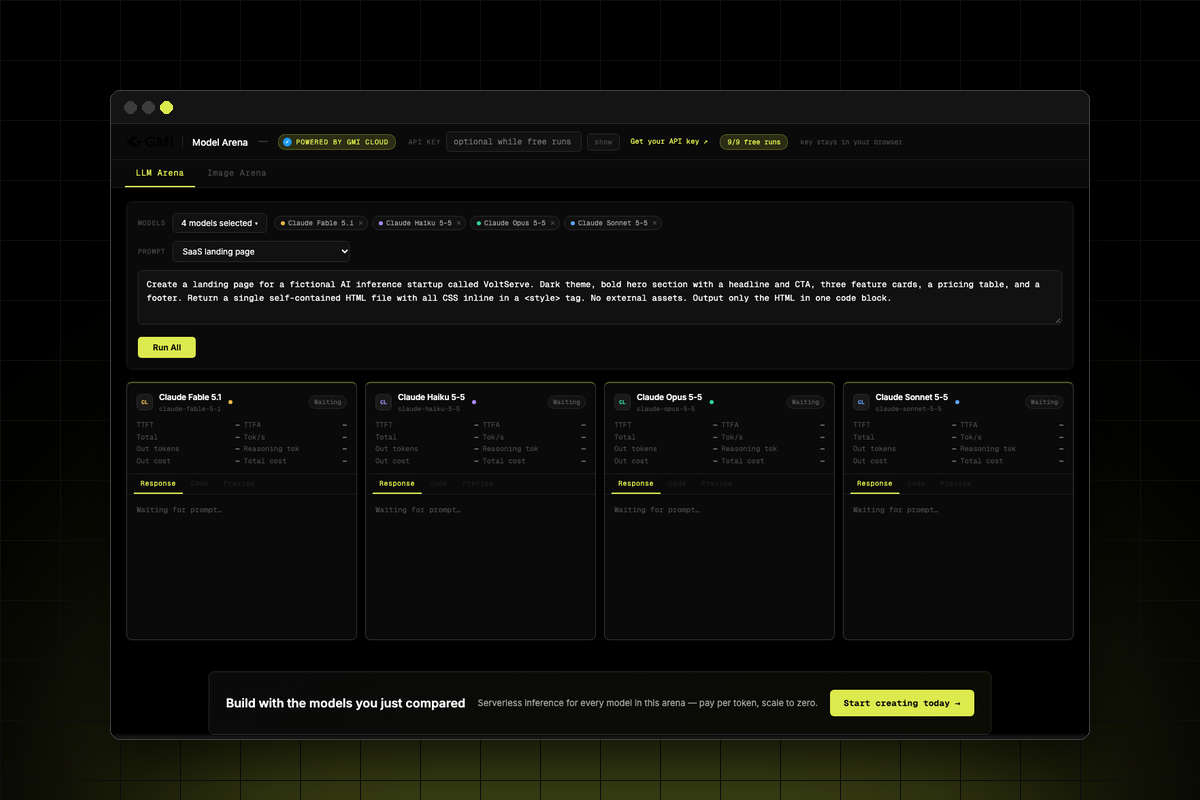
Model Arena
Same prompt, N models: compare top LLMs side by side with streaming, code preview, latency and cost, plus an image arena.
Each demo runs on the same API and compute you build with. Open one, then read the docs.
Built by the GMI Cloud community and GMI DevRel. 49 demos, each one a small app that calls GMI inference and returns a result.
Same prompt, N models: compare top LLMs side by side with streaming, code preview, latency and cost, plus an image arena.
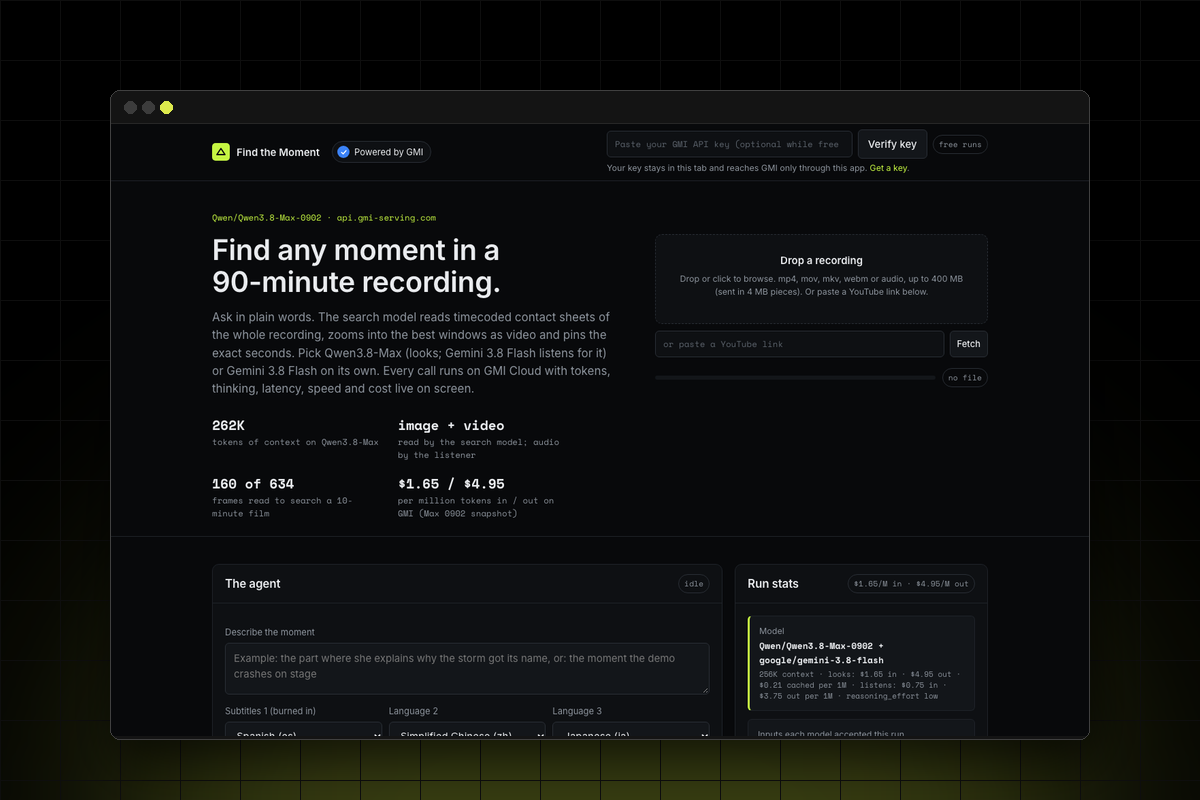
Drop a long recording, ask a question: a vision agent searches it coarse-to-fine, cuts the clip, subtitles it in three languages, optional Omni remix.
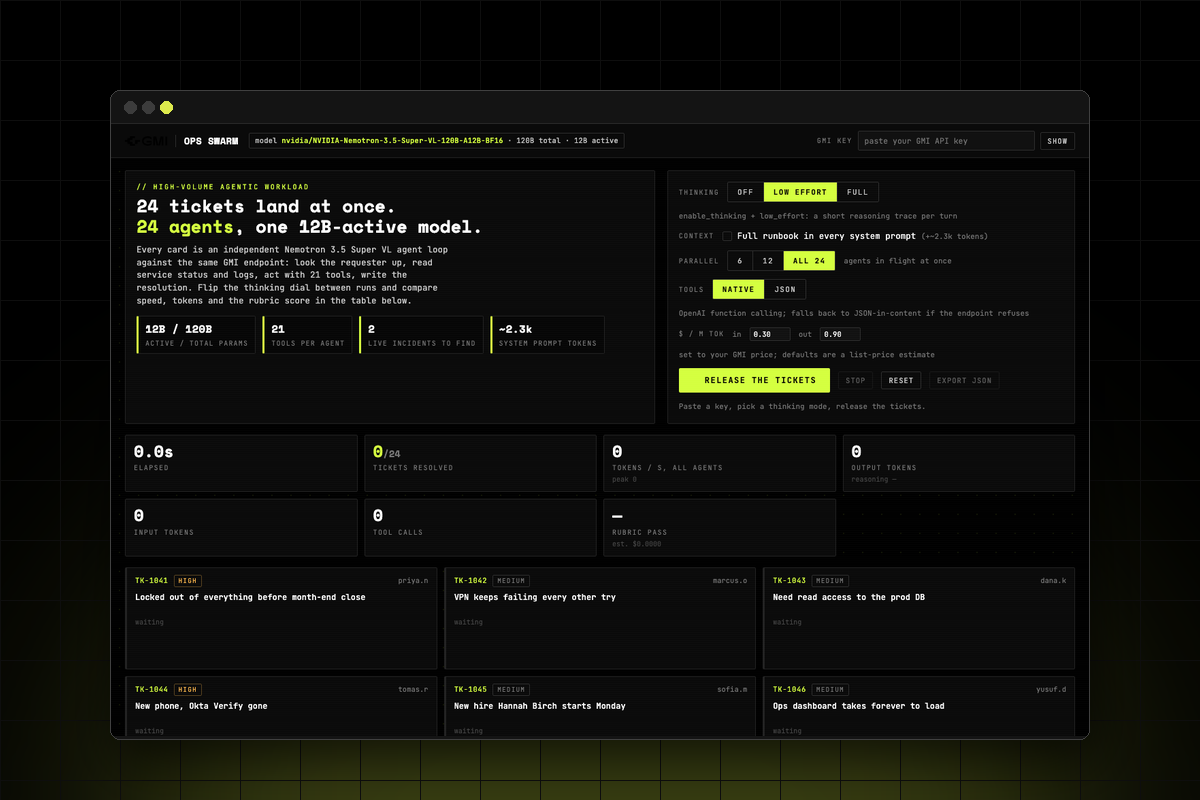
24 IT tickets handled by 24 parallel Nemotron agents with 21 mock tools, a thinking-mode dial and comparison runs.
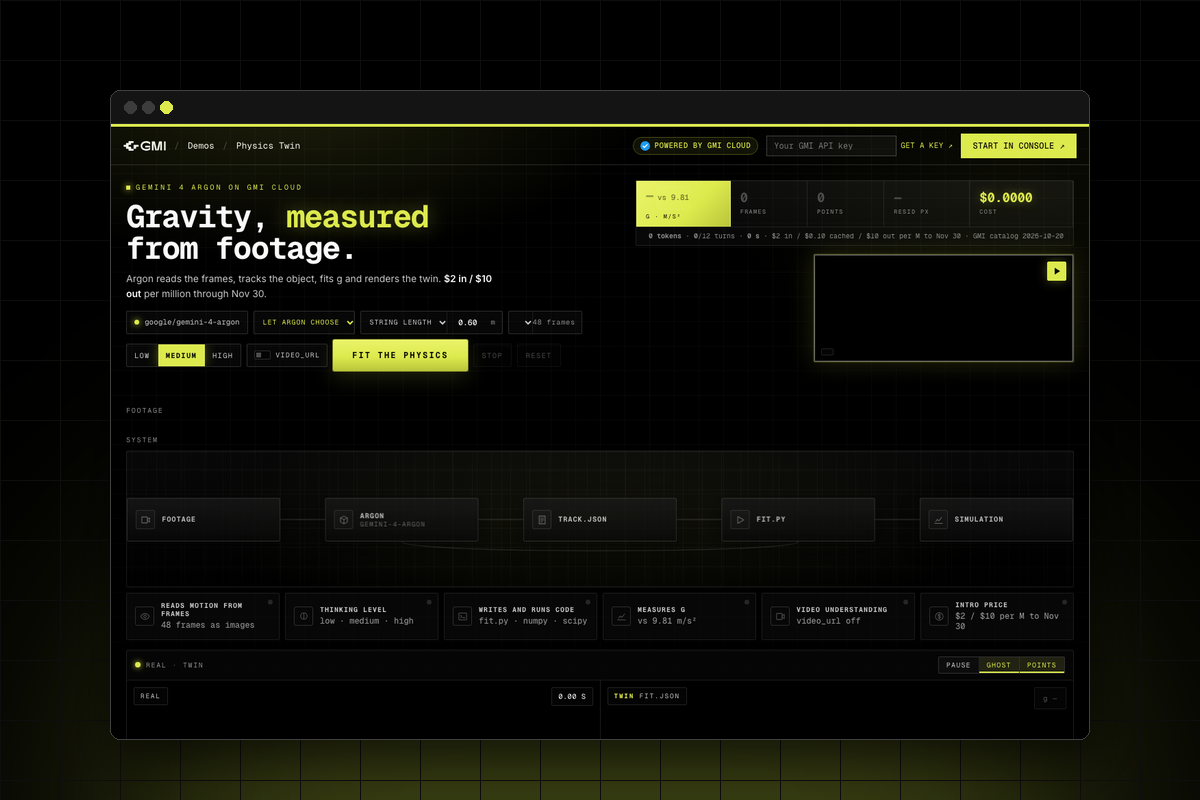
Footage in, physics out: Gemini 4 Argon tracks a moving object across 48 frames, writes and runs the fit, and puts its g next to 9.81 with an error bar.
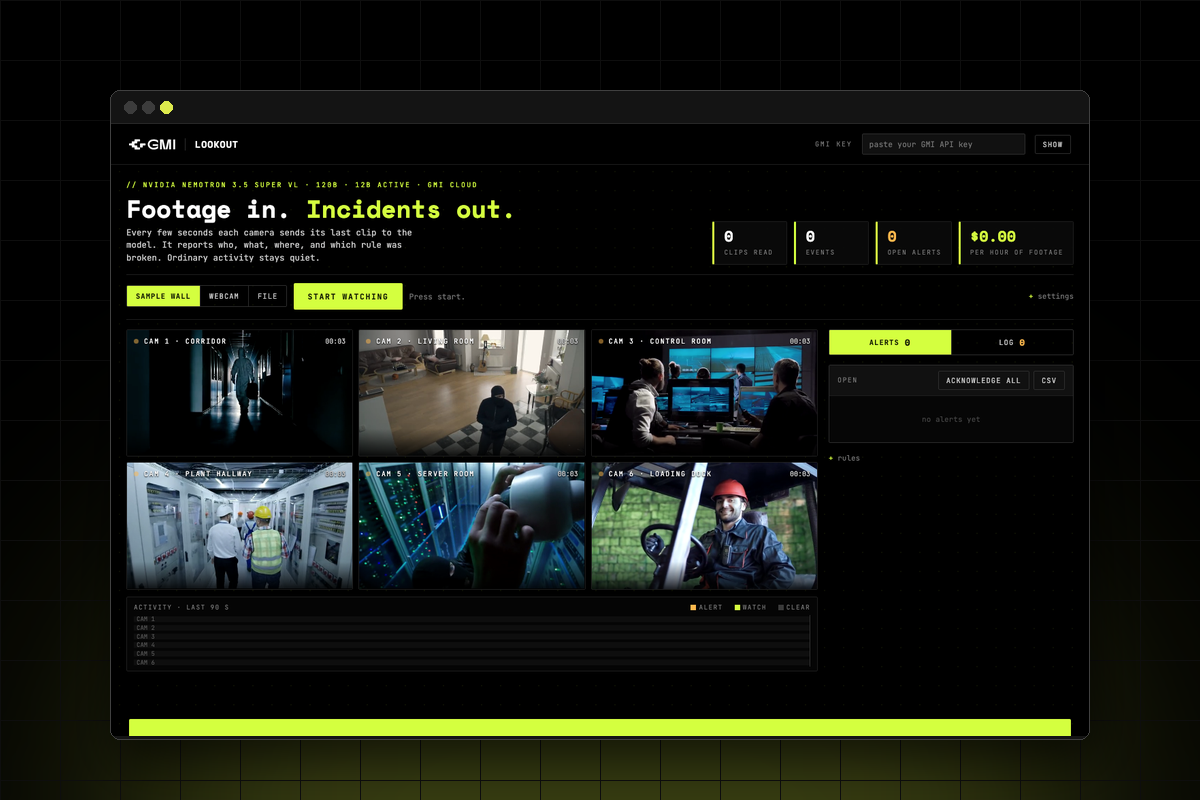
A security camera wall: six-second clips go to Nemotron 3.5 Super VL, which returns events, positions and rule-breaking alerts.
One sentence in, one image out: Gemini 4 Argon writes the image prompt, Nano Banana 2.1 renders it on GMI Cloud. Covers, wallpapers, ads, photo edits.
Audio description for blind viewers: MiniMax M3.1-Flash reads the frames, writes one line per silent gap, the browser speaks it in the gap. WebVTT out.
Turns a GitHub repo into a two-host podcast: Qwen3.8 writes the script, two GMI TTS voices read it, the browser mixes the audio.
NVIDIA's CFO commentary plays as a ticker while Step 5 Preview ties every number to the 10-Q: all 43 filing pages as images plus text in one request.